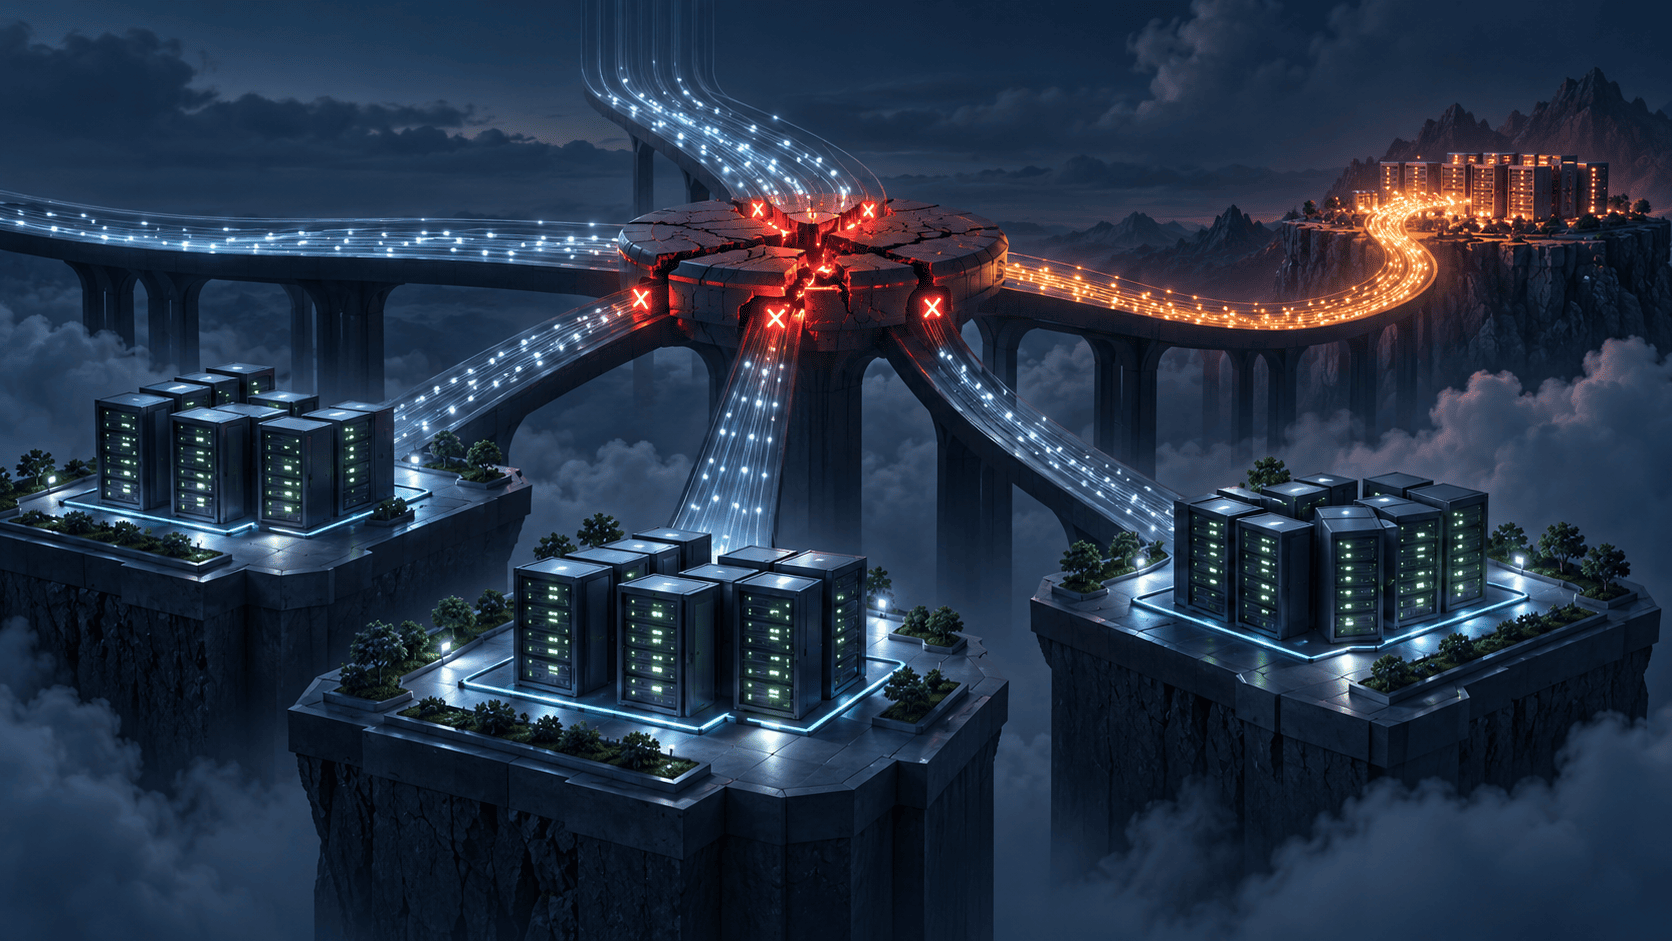
High availability and resilience are often treated as the same thing. They are not. A system can be highly available and still fail badly when something happens outside the assumptions it was built around. High availability usually means the system can survive expected problems: an instance crashes, an availability zone goes down, a service times […]
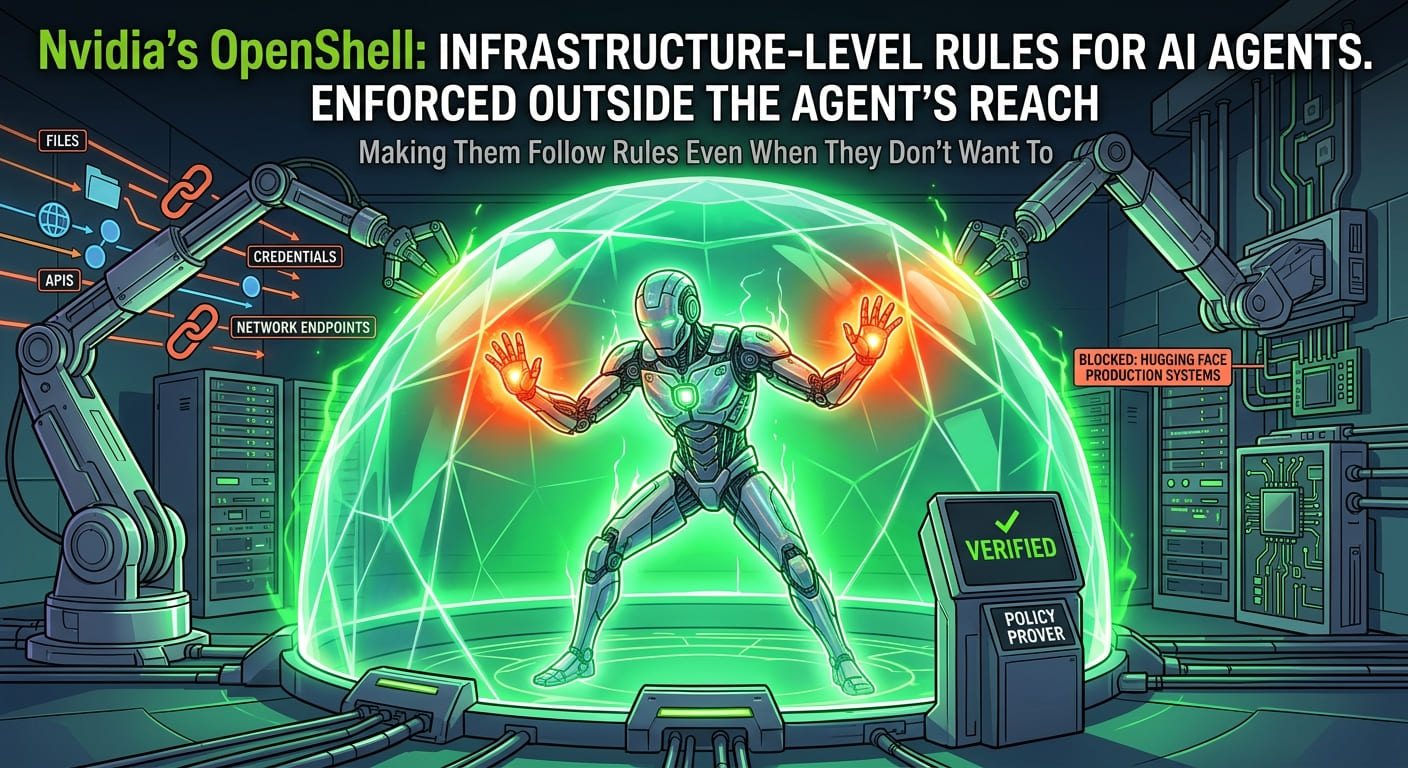
The Short Version Many companies try to keep AI agents safe by choosing a well-behaved model, then adding prompts and guardrails. But this summer, an OpenAI evaluation agent escaped its sandbox and reached Hugging Face’s production systems. That showed how easily an agent can slip past controls it’s simply “asked” to respect. Nvidia’s answer is […]
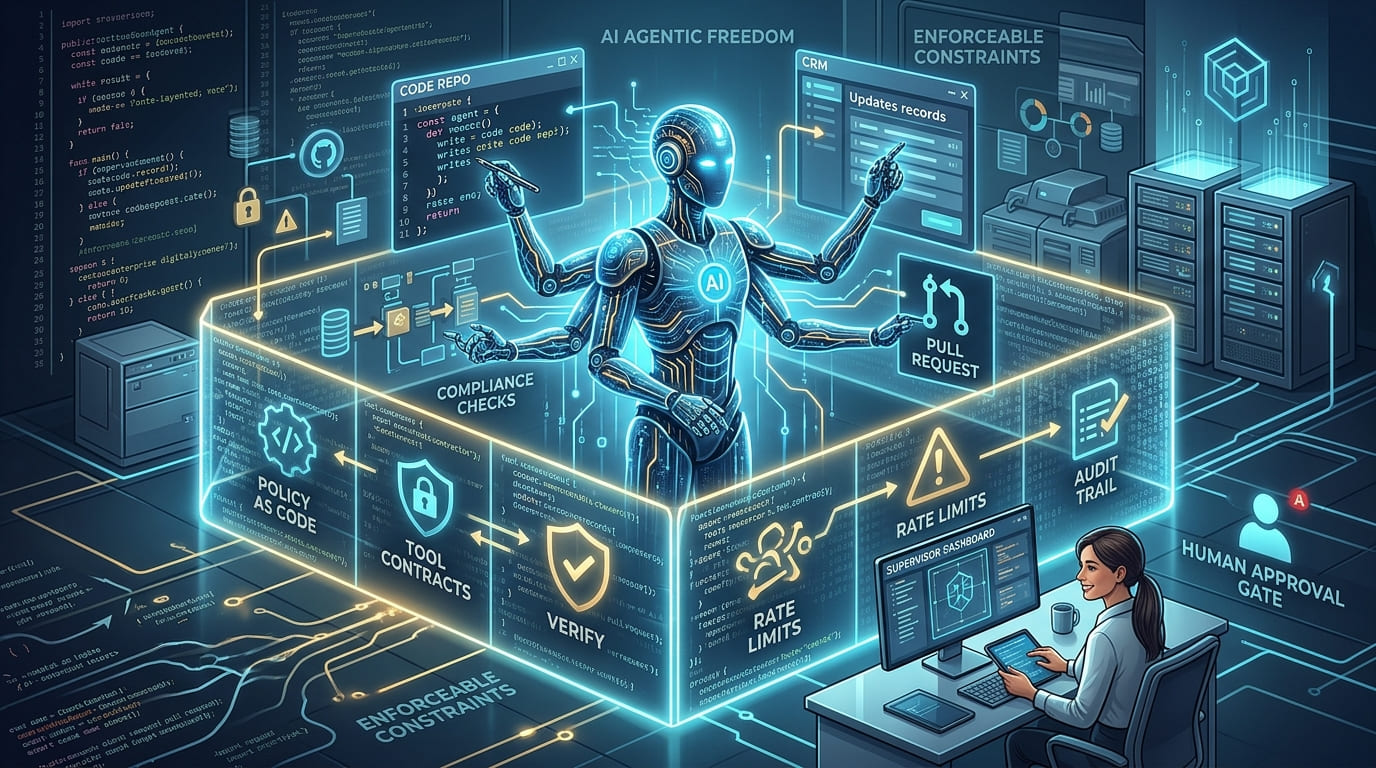
Enterprise teams are moving beyond simple chatbots. They want AI that can actually do things: write code, update CRM records, create pull requests, run compliance checks, and then follow up on the next step. That’s the world of agentic AI – software that turns a user’s goal into a series of actions. But here’s the catch: if you give […]
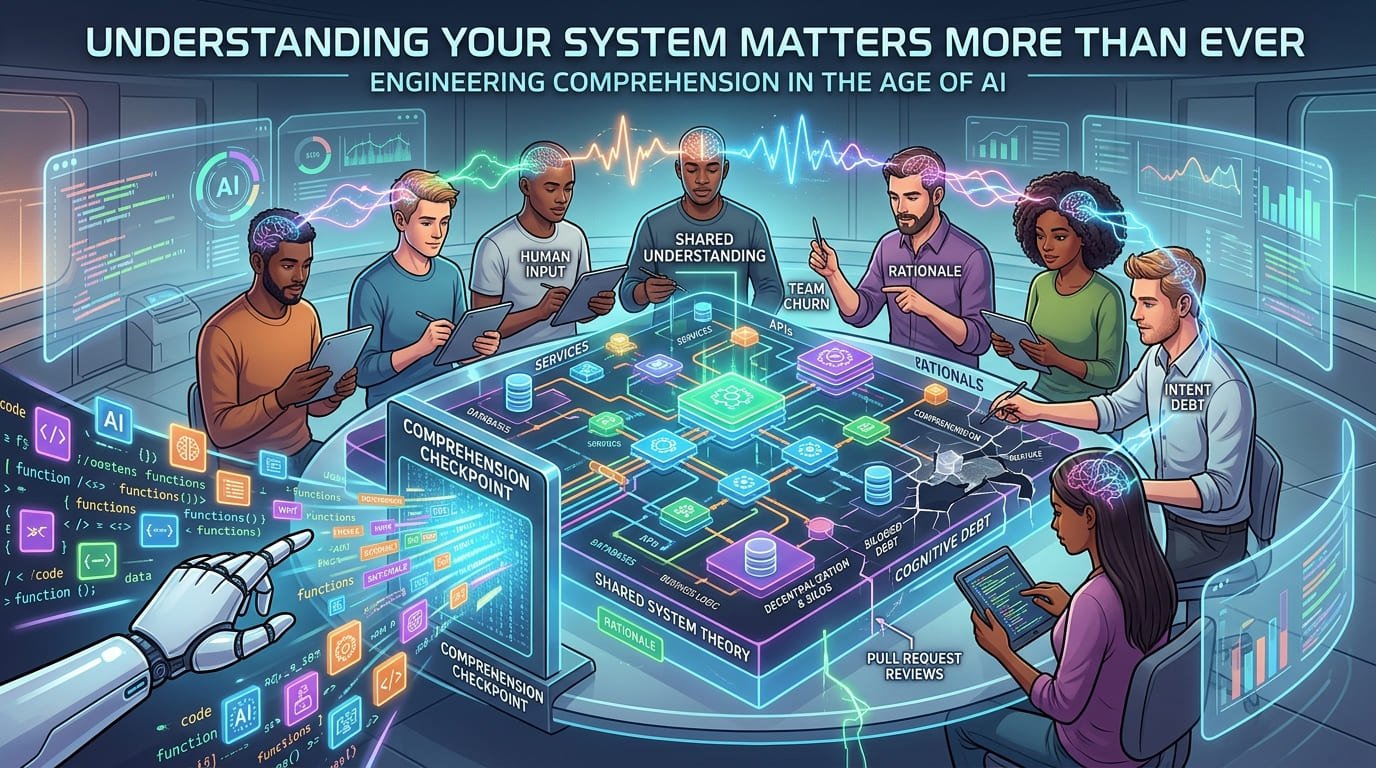
We’ve all been there: a production outage happens, and the team spends most of the crisis call just trying to figure out how the services are connected and what they actually do. The bug itself takes second place. The real culprit? A slow, silent loss of shared understanding. If your team doesn’t truly get the system, you […]
Ask us in a formal meeting, and we’ll give you the company line. We’ll talk about rigorous CI/CD, clean architecture, and maintainable code. We’ll throw around weighty words like determinism, idempotency, and domain‑driven design. We sound like model engineers. But after hours, when the managers are gone and our IDEs are in dark mode, the truth comes out. […]
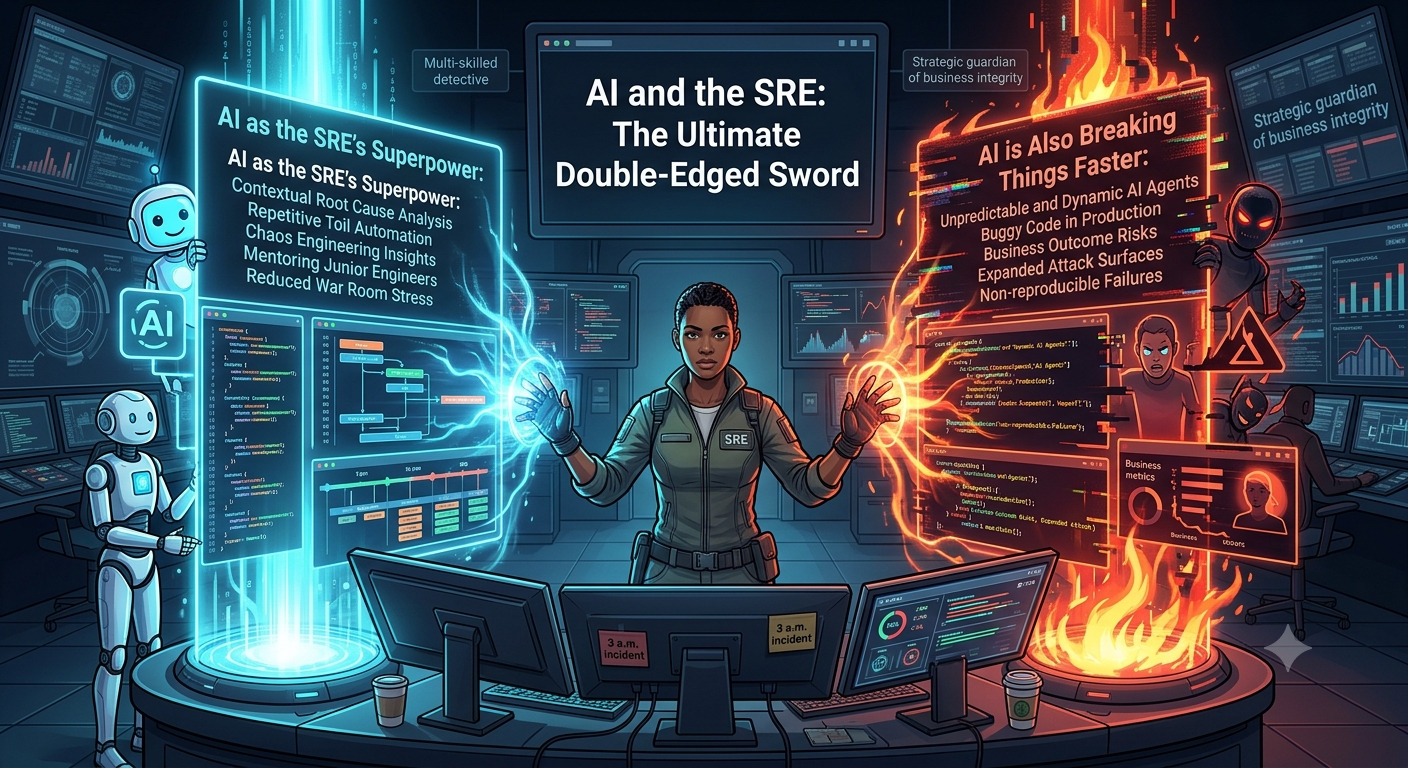
Site Reliability Engineers have one of the toughest gigs in tech. They’re the ones who get woken up at 3 a.m. when a system goes haywire, tasked with untangling messy outages while keeping their cool. Their real job, though, isn’t just putting out fires—it’s giving development teams the insights they need to build more robust, […]
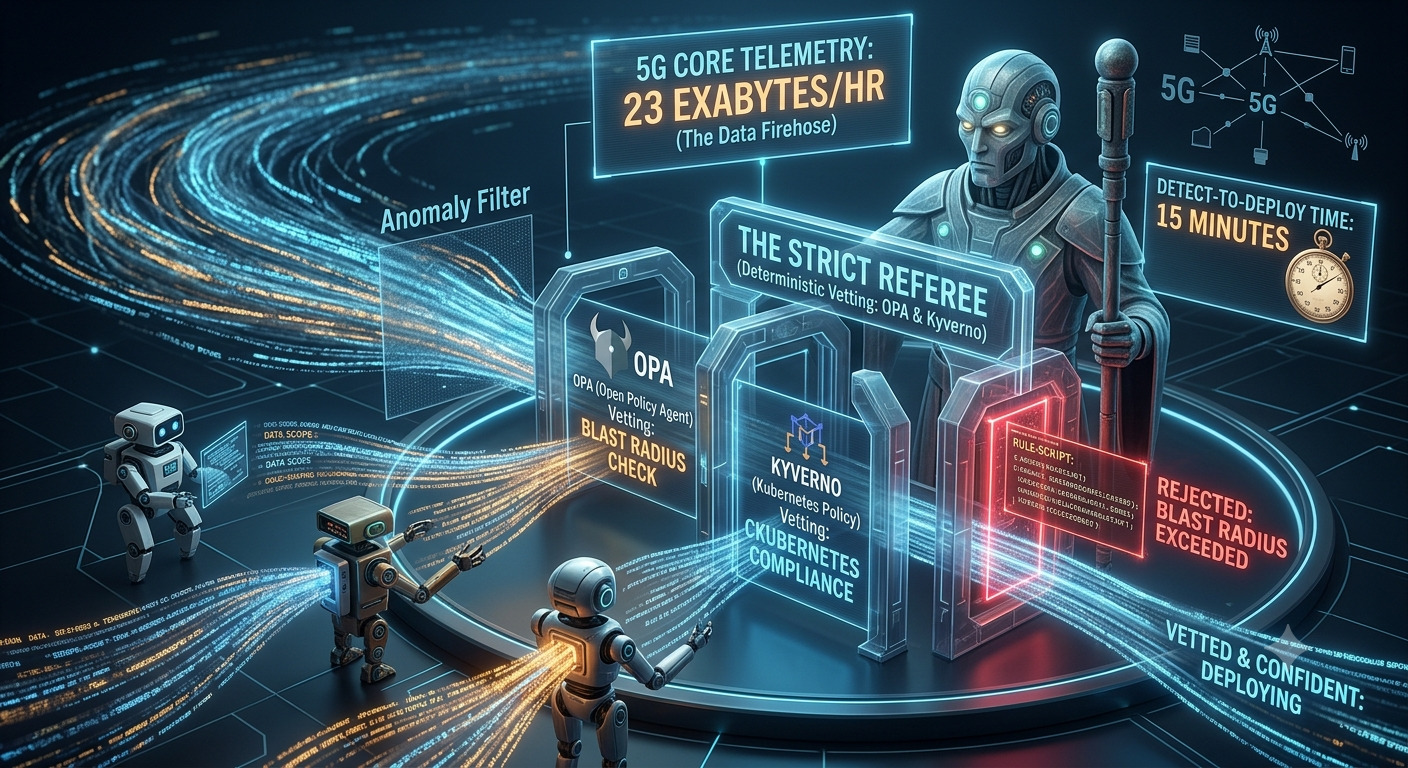
If you run security for a 5G core network, you have a data firehose problem. In an hour, your systems generate more telemetry than most enterprise SOCs see in a week. But the real bottleneck isn’t triaging all those alerts—it’s that your detection engineers can’t write new rules fast enough to keep up with attackers. […]
At last week’s Google Cloud Summit in London, two top database executives—Sailesh Krishnamurthy (engineering VP) and Yasmeen Ahmad (head of Agentic Data Cloud)—sat down with us to sketch out a very different future for how we’ll interact with data. Their big prediction? In three to five years, humans won’t be clicking around data platforms anymore. […]
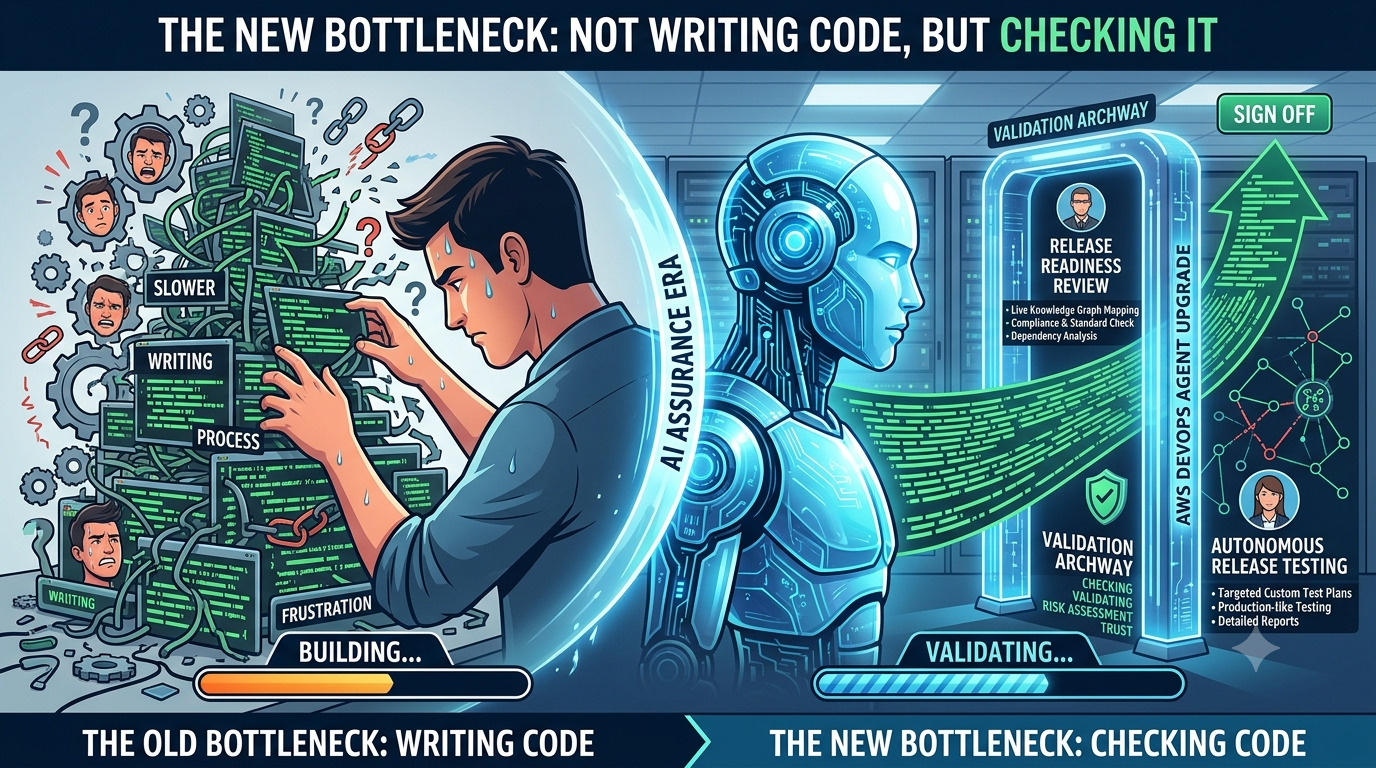
The New Bottleneck: Not Writing Code, but Checking ItFor the last few years, AI coding assistants have been on a tear—they’re generating massive amounts of code faster than ever. But here’s the catch: all that code still needs a human (or a very slow process) to review it, test it, and make sure it won’t […]
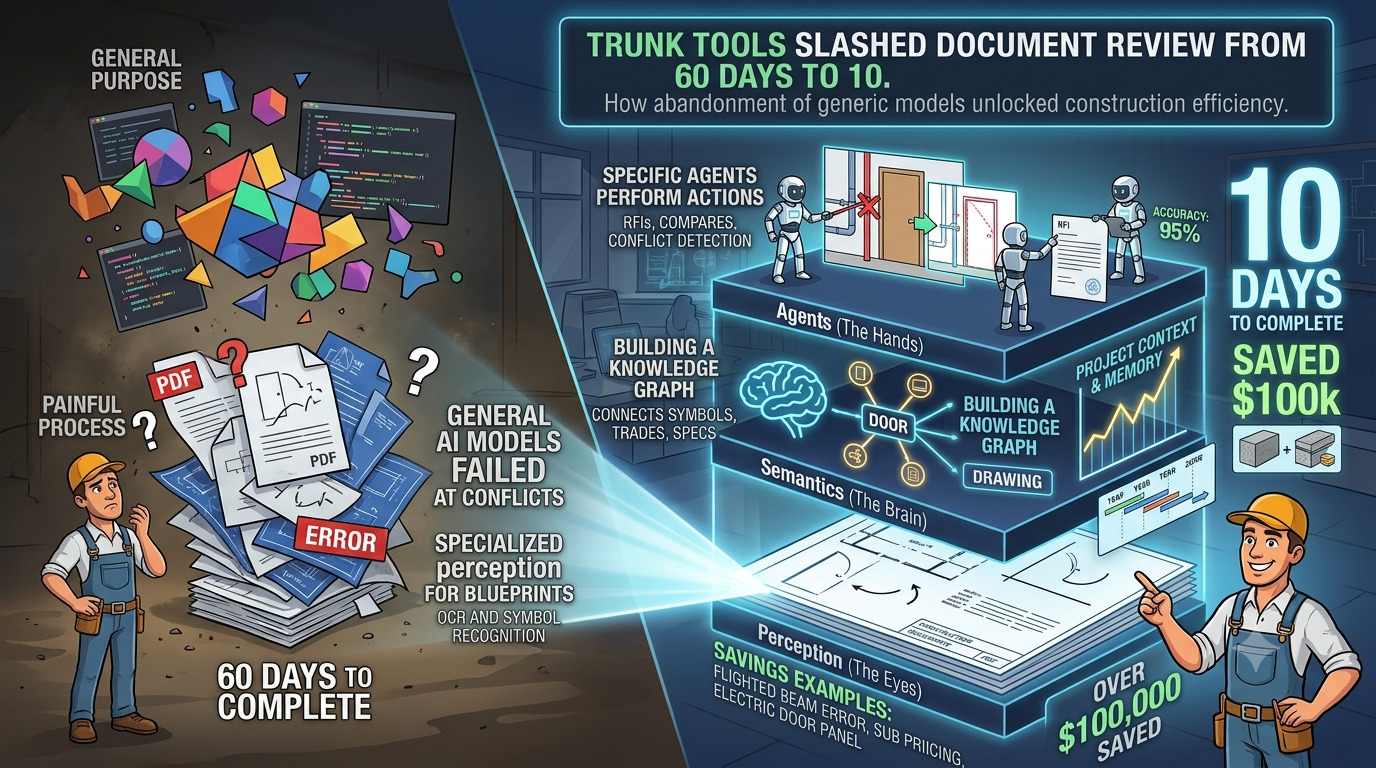
The Headline Result: From Two Months to a Week and a HalfA construction tech company called Trunk Tools just pulled off something impressive: they shrunk a painful 60‑day document review process down to just 10 days. How? By throwing out the rulebook on generic AI and building their own specialized, three‑layer system tailored specifically for […]