High Availability Is Not Resilience: Why Cloud Systems Fail When It Matters Most
High availability and resilience are often treated as the same thing. They are not. A system can be highly available and still fail badly when something happens outside the assumptions it was built around.
High availability usually means the system can survive expected problems: an instance crashes, an availability zone goes down, a service times out. Resilience means the system can recover when reality throws something at it that nobody planned for. That difference matters, because many cloud systems look strong on an architecture diagram but have never actually proved they can recover under pressure.
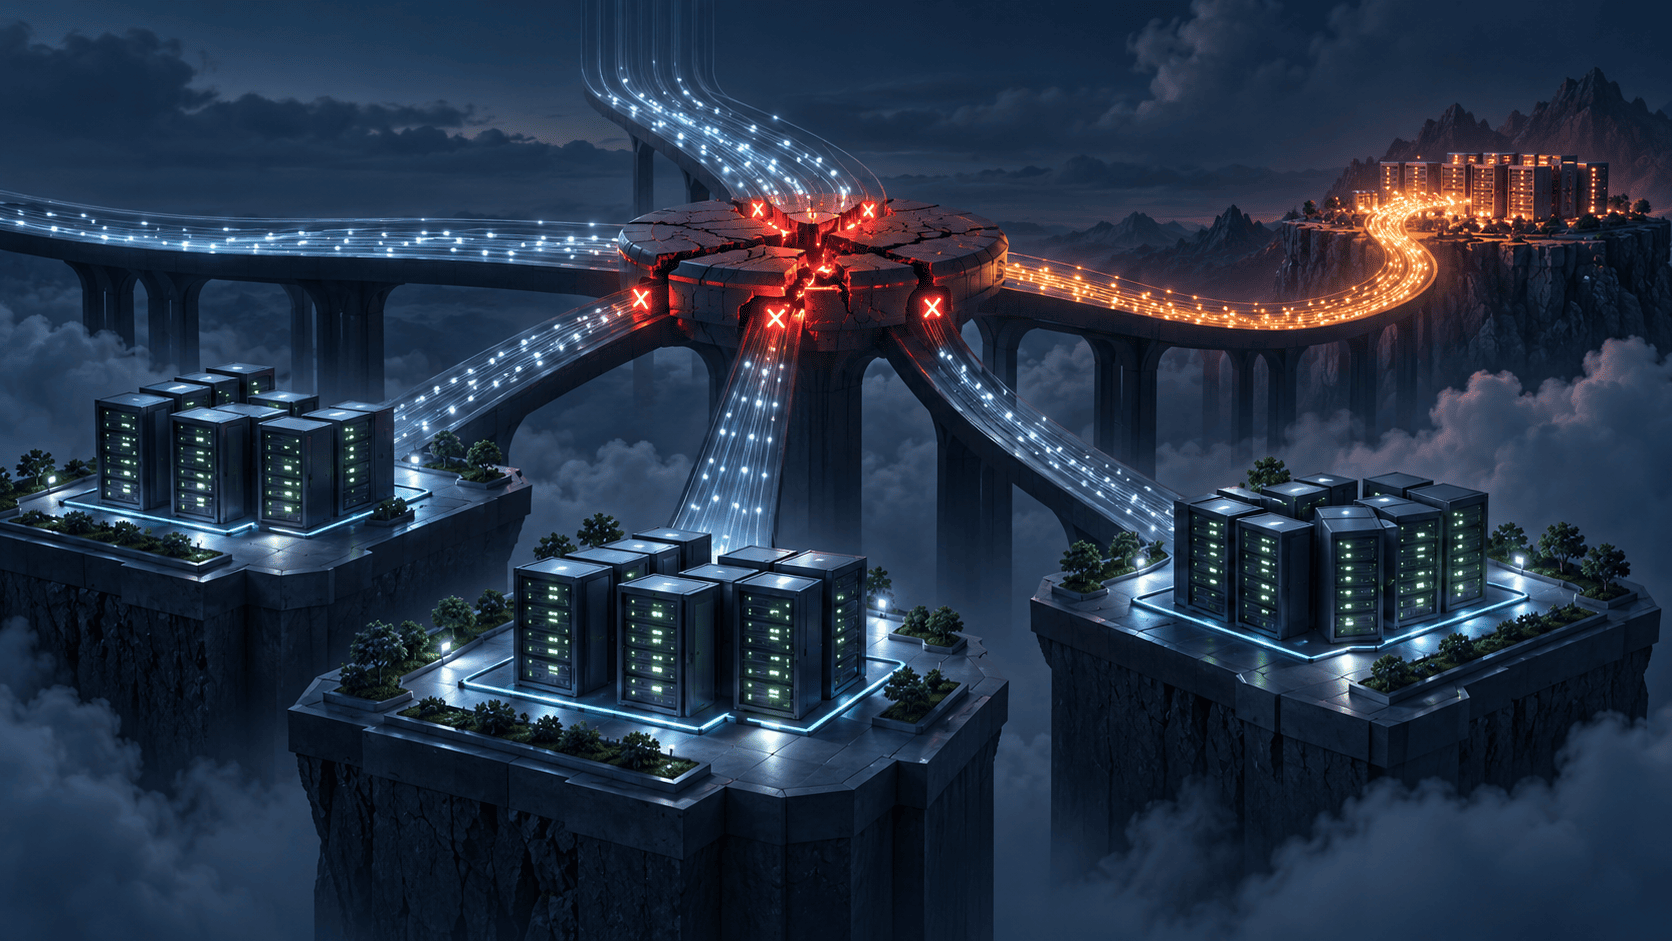
A good example comes from a team that upgraded its public ingress load balancers to TLS 1.3 for compliance. At first, everything looked fine. Handshakes worked, services stayed healthy, and dashboards were quiet. But Route 53 HTTPS health checks at the time required TLS 1.2. When TLS 1.2 was disabled, the health checker could not complete its handshake, so it marked the endpoint unhealthy. The CDN then decided the whole region was unhealthy and stopped sending traffic there.
Inside the region, nothing looked broken. The services were running, the load balancers were healthy, and applications could still serve requests. The only real symptom was that traffic had stopped arriving. Users were silently sent to another region far away. Latency rose. The failover region began scaling for load it was never sized for. Synthetic monitoring eventually showed a pattern that internal telemetry could not see. It took about forty minutes to isolate the problem.
The failure was not in the application data plane. It was in the control plane: the part of the system that decides where traffic should go. The system was highly available, but it was not resilient.
Availability and Resilience Are Different Problems
Cloud platforms make high availability fairly easy. Managed databases can fail over across availability zones. Autoscaling groups sit behind load balancers. CDNs absorb traffic and hide regional problems. These patterns work well when failures stay inside the design assumptions: an instance dies, a zone disappears, a dependency times out.
Real incidents rarely respect those assumptions. High-availability engineering assumes failures are isolated and predictable. Resilience engineering assumes the opposite: eventually, something critical will fail in a way nobody modeled. Redundancy alone is not enough. A failover path that has never been tested is not a recovery strategy. It is only an assumption.
Three patterns show the gap clearly.
1. Correlated failures can defeat redundancy.
Multi-AZ designs handle a zone failure, but they do not automatically handle software-level correlation. A bad config push can hit every replica at once. A poisoned cache record can be served from every read replica. A dependency upgrade can silently break a contract the whole system relies on. When independence disappears, redundancy stops working as insurance.
2. Graceful degradation is often untested.
Most teams assume their system degrades gracefully, but few have tested it under realistic load. If a read replica falls behind, does the cache layer absorb the pressure or amplify it onto the primary? Until it is exercised, graceful degradation is a hypothesis, not a guarantee.
3. Recovery paths rot.
A system may run for years while its rebuild runbook was written before half its current dependencies existed. IAM policies drift. Deployment tooling changes. Recovery is a code path like any other, and unused code paths decay.
The Organizational Problem Shows Up Before the Incident
Resilience is not only architectural. It is organizational. Uptime ownership is usually clear: on-call rotations, SLOs, escalation paths. Recovery ownership is often vague. Few organizations have a named recovery owner, a regular testing cadence, or a process for keeping runbooks current as infrastructure changes. That gap is rarely a deliberate decision. It is what happens when nobody owns it.
Closing the gap is expensive. Testing the scenarios that matter requires engineering time, operational risk, and infrastructure kept ready for events that may never happen. So many teams drift toward performative resilience: the architecture diagram looks right, the standby region exists, and the runbook exists. Actual recovery capability is assumed rather than demonstrated. The first thirty minutes of a major incident are often spent doing “dependency archaeology”: discovering that permissions have drifted, runbooks point to retired tools, and nobody is sure who still understands the standby environment.
The fix is not glamorous. Recovery needs an explicit owner, separate from on-call. On-call is about response. Recovery ownership is about preparation: the procedure, the tooling, and the responsibility to keep both current. Teams that recover well treat failover drills as recurring engineering work. They start small—one service, one AZ shift—and every exercise finds something broken: a revoked permission, a stale runbook, a silent alarm. Recovery has to be maintained, not assumed.
Five Questions for Recovery
You do not need to redesign everything to start testing resilience. Ask five questions:
- What fails first? Identify the control-plane dependencies your recovery path relies on: DNS, identity, routing, certificates, configuration, orchestration, and third-party services.
- What would the team actually observe? For each failure scenario, define the signal that would tell you something is wrong. A green application dashboard is not enough if the failure happens before requests reach the application.
- Can you execute the recovery path? Test the real mechanism, not the diagram. If failover depends on a DNS change, routing decision, or control-plane API, exercise that path under realistic conditions.
- Who owns recovery? The on-call engineer responds to incidents. Someone else should own keeping recovery mechanisms, runbooks, dependencies, and tests current.
- What changed after the last test? Record what failed, what was surprising, and what assumptions proved wrong. Turn those findings into engineering work.
The goal is not to test every possible failure. It is to regularly challenge the assumptions that make recovery possible.
The Control-Plane Trap Nobody Draws
Most cloud failover discussions focus on the data plane: where traffic goes, which region handles requests, and what happens when an instance dies. The control plane—the system that decides where traffic should flow—gets much less attention. The TLS 1.3 incident was exactly that kind of failure. The data plane worked perfectly. The control plane broke.
From inside the service, nothing looked wrong. The service and load balancer were healthy. Traffic simply was not arriving. Synthetic monitoring showed a divergence that internal telemetry could not, because internal telemetry only watched the data plane. The failure was visible only from outside, through monitoring infrastructure that was itself part of the control plane.
This is the structural problem with control-plane dependencies: they are invisible in normal operation. CDN health checks feel like monitoring, but if they gate traffic, they are part of the data path even though they live in the control plane. When they break, the data plane is fine and the service is unreachable.
The pattern repeats across cloud services. AWS STS is a well-known example. The global endpoint at sts.amazonaws.com is hosted in a single AWS Region, US East (N. Virginia), and does not automatically fail over to other regions. Many services that look global still carry a regional dependency that does not appear on standard architecture diagrams. If that region degrades, the global service can fail in ways that bypass regional redundancy.
Many multi-region architectures are therefore multi-region only in the data plane. Their recovery assumptions still collapse onto a small number of shared control-plane dependencies. The right question is not just “What happens if a region fails?” It is also “What happens if the thing that detects regional failure is itself degraded?”
After the TLS incident, two alerting gaps were found. The CDN had moved traffic away from an entire region without triggering an alert. The load balancers had dropped to zero inbound traffic just as silently. The failure was caught only because an engineer happened to be watching metrics during the rollout. It also turned out that the CDN had been silently failing health checks for a week on the first batch of upgraded load balancers, while traffic continued to flow normally on the remaining TLS 1.2 targets. Nobody had known.
ARC Versus DNS-Based Failover
If control-plane dependencies are an accepted risk, the question is what to do about them. The two main options are AWS Application Recovery Controller (ARC) and traditional DNS-based failover through Route 53 health checks. They sound similar, but they are not.
DNS-based failover is the default. Route 53 probes endpoints, marks them healthy or unhealthy, and updates DNS records. It is simple, widely understood, and cheap. But if you need sub-minute recovery, DNS becomes uncomfortable. DNS propagation delays, TTLs, recursive resolvers, and aggressive client caching all become part of your recovery window. Add the control-plane dependency described above, and the picture gets worse. If Route 53’s health check infrastructure degrades, failover may not trigger—or it may trigger incorrectly.
ARC takes a different approach. Instead of DNS, it provides routing controls you flip explicitly when you decide to fail over. It also runs continuous readiness checks so you know whether the failover target can actually accept load before you flip. ARC’s routing control plane is a cluster of five regional endpoints designed to remain operable during regional impairment. ARC does not remove complexity. It moves complexity into a more explicit and dedicated operational model.
Key differences:
- Speed: DNS is bounded by health check intervals, propagation delay, and client TTLs—usually minutes, sometimes longer. ARC operates in seconds.
- Failure modes: DNS failover depends on Route 53 health check accuracy. ARC’s five-region endpoint cluster means a routing control flip does not require any single control plane to be healthy.
- Operational complexity: DNS is familiar. ARC is heavier. Routing controls and readiness checks require dedicated ownership, current runbooks, and on-call staff who know how to execute a flip under pressure.
- Cost: DNS is effectively free. ARC charges per cluster and per control. It is not expensive for one critical service, but it adds up.
- Pre-failover confidence: ARC’s readiness checks continuously validate that the target can accept traffic. With DNS, you often find out at failover time.
A tiered approach works well: use ARC for a small set of customer-facing critical paths where control-plane dependency is unacceptable, and use DNS for everything else. Payment flows, authentication, and core booking paths may justify ARC. Internal tools and low-traffic APIs usually do not.
Recovery Is a Capability, Not a Property
Recovery capability is not something an organization discovers during an incident. By then, it has already been built or neglected months earlier.
Resilience cannot be fully proved. High availability has benchmarks: uptime, redundancy, failover timing, replication lag. Resilience is adversarial. Correlated failures, stale runbooks, control-plane coupling, and human coordination under stress often surface only under conditions too expensive or too risky to reproduce reliably. Full regional failover under production load, or recovery from a corrupted primary with real users waiting, is not something most teams can routinely test without accepting significant operational risk. That is why performative resilience is so common. It is not because teams are careless. It is because the bar for genuine proof is genuinely high.
The honest goal is not to guarantee recovery. In sufficiently complex systems, resilience is probabilistic, not provable. The realistic target is to improve confidence by reducing unknowns, rehearsing coordination, narrowing the blast radius, and shortening the gap between failure and detection. Architecture diagrams look resilient because components are redundant. But resilience is not determined by how the diagram looks under normal conditions. It is determined by whether people can actually recover the system under pressure, with degraded visibility, incomplete context, and dependencies that are not behaving as expected.
Most organizations eventually discover that the recovery procedures they never exercised are the ones that fail first. That gap is not visible in the architecture. It becomes visible the first time the recovery path has to actually be used.
Sylvia
October 21, 2026Recovery ownership must be explicit. On-call response is not the same as owning recovery preparation. Without a named owner, recurring tests, and maintained runbooks, resilience becomes a story people tell until the first real failover.